Chapter 1: Why turn text into a picture?↗
Text visualization can begin with four questions. How can a reader grasp the outline of a document? Compare documents or follow their evolution? Find an entry point for grouping and topic exploration? Relate textual patterns to other data?
A picture does not guarantee faster or more accurate reading. It brings some relations forward while hiding others. Decide what needs to become visible before choosing how to compress the text.
1.1 What kind of data is text?↗
Web pages, articles, logs, books, email, comments, source code and tags can all be documents. Organizing them by author, time, community or task produces different collections.
| Characteristic | Implication for visualization |
|---|---|
| Abstraction | Characters need not resemble what they refer to |
| Sequence | Word order can change meaning; prose is usually read sequentially |
| Multiple levels | Words, sentences, paragraphs, grammar and typography offer different units of analysis |
| Variation across groups and settings | The same word can serve different purposes across communities, genres and contexts |
1.2 More than too many words↗
| Challenge | What must be decided? |
|---|---|
| High dimensionality | Which terms, relations and levels should survive? |
| Keywords | Are frequency, distinctiveness and descriptiveness the same thing? |
| Context | How much text preserves negation, modification and whom a statement addresses? |
| Meaning | How should ambiguous forms, synonyms and metaphor be handled? |
| Access to the source | Can readers return from the view to the relevant passage? |
| Domain structure | Does a classification or ontology require additional domain knowledge? |
Terms can be counted as categories without reducing their meanings to equality tests. Paris, New York and Madrid share a city category; that list alone establishes no statistical correlation. January, February and March have a calendar order, but arbitrary vocabularies have no natural ordering. Inflection is also different from synonymy, antonymy and hierarchical relations.
Chapter 2: Processing is not one fixed pipeline↗
Tokenization, entity recognition, stemming and lemmatization are different operations. They can be combined without always running every step in one order. Stemming and lemmatization are often alternatives chosen for a task.
| Operation | Purpose | Example and boundary |
|---|---|---|
| Tokenization | Segment characters into tokens while retaining alignment with the source | “a sentence” can yield two tokens; punctuation may also be retained |
| Filtering | Decide whether to remove stop words, numbers or symbols | This is not the definition of tokenization; negation and prepositions may be the object of study |
| Named entity recognition | Identify spans referring to people, organizations, places and other categories | James Bond may be tagged as a person; categories depend on the model and annotation scheme |
| Stemming | Merge some forms through rules; the result need not be a complete word | fishing and fished may reduce to fish; rules differ |
| Lemmatization | Recover a base form using dictionaries, rules or models | went can map to go; results may depend on part of speech and context |
| Vocabulary indexing | Assign computational identifiers to terms | The IDs for go and good encode no magnitude, distance or semantic order |
spaCy’s linguistic-feature documentation distinguishes these operations. Informal text, abbreviations, names and multiword entities need separate attention. Preserve surface forms or source offsets for presentation: a stem generally cannot be uniquely reversed.
Tools such as Gensim and spaCy can help implement the processing, but the unit of analysis comes first. If the question concerns “X and Y,” deleting and at the start removes the very connection the later network is meant to find.
Chapter 3: Bags, matrices and clouds↗
3.1 A document as a vector↗
A basic bag-of-words representation counts terms while discarding their positions. It may use unigrams or extend to n-grams. The latter preserve local order without preserving the arrangement of all phrases in the document. Omitting order from a representation does not assert that terms are statistically independent.
For documents and a vocabulary of terms, a document–term count matrix can be written as:
Rows represent documents and columns represent terms. scikit-learn’s text-feature guide uses this convention. The original note’s transposed layout below makes the plays easier to compare. Its values come from a teaching table in the related lecture, rather than a corpus recounted for this revision.
| Term | Antony and Cleopatra | Julius Caesar | The Tempest | Hamlet | Othello | Macbeth |
|---|---|---|---|---|---|---|
| Antony | 157 | 73 | 0 | 0 | 0 | 0 |
| Brutus | 4 | 157 | 0 | 1 | 0 | 0 |
| Caesar | 232 | 227 | 0 | 2 | 1 | 1 |
| Calpurnia | 0 | 10 | 0 | 0 | 0 | 0 |
| Cleopatra | 57 | 0 | 0 | 0 | 0 | 0 |
| mercy | 2 | 0 | 3 | 5 | 5 | 1 |
| worser | 2 | 0 | 1 | 1 | 1 | 0 |
Counts are only one weighting scheme. Relative frequency, , can help compare documents of different lengths when the denominator is positive. TF–IDF answers another question. Frequency, distinctiveness and usefulness to a reader are not interchangeable.
3.2 Word clouds: visibility has a cost↗
Tag clouds commonly encode frequency or another weight through type size. They can suggest a useful query without supporting precise comparisons.
| What they can support | What they can obscure |
|---|---|
| Finding prominent terms | Grammar, relations and negation |
| Forming a query | Size and arbitrary placement are often harder to compare than positions on a shared scale |
| Quick scanning | Longer words occupy more area without necessarily having greater weight |
| An overview | Unstable layouts complicate comparisons between documents |
3.3 Recovering a modifier↗
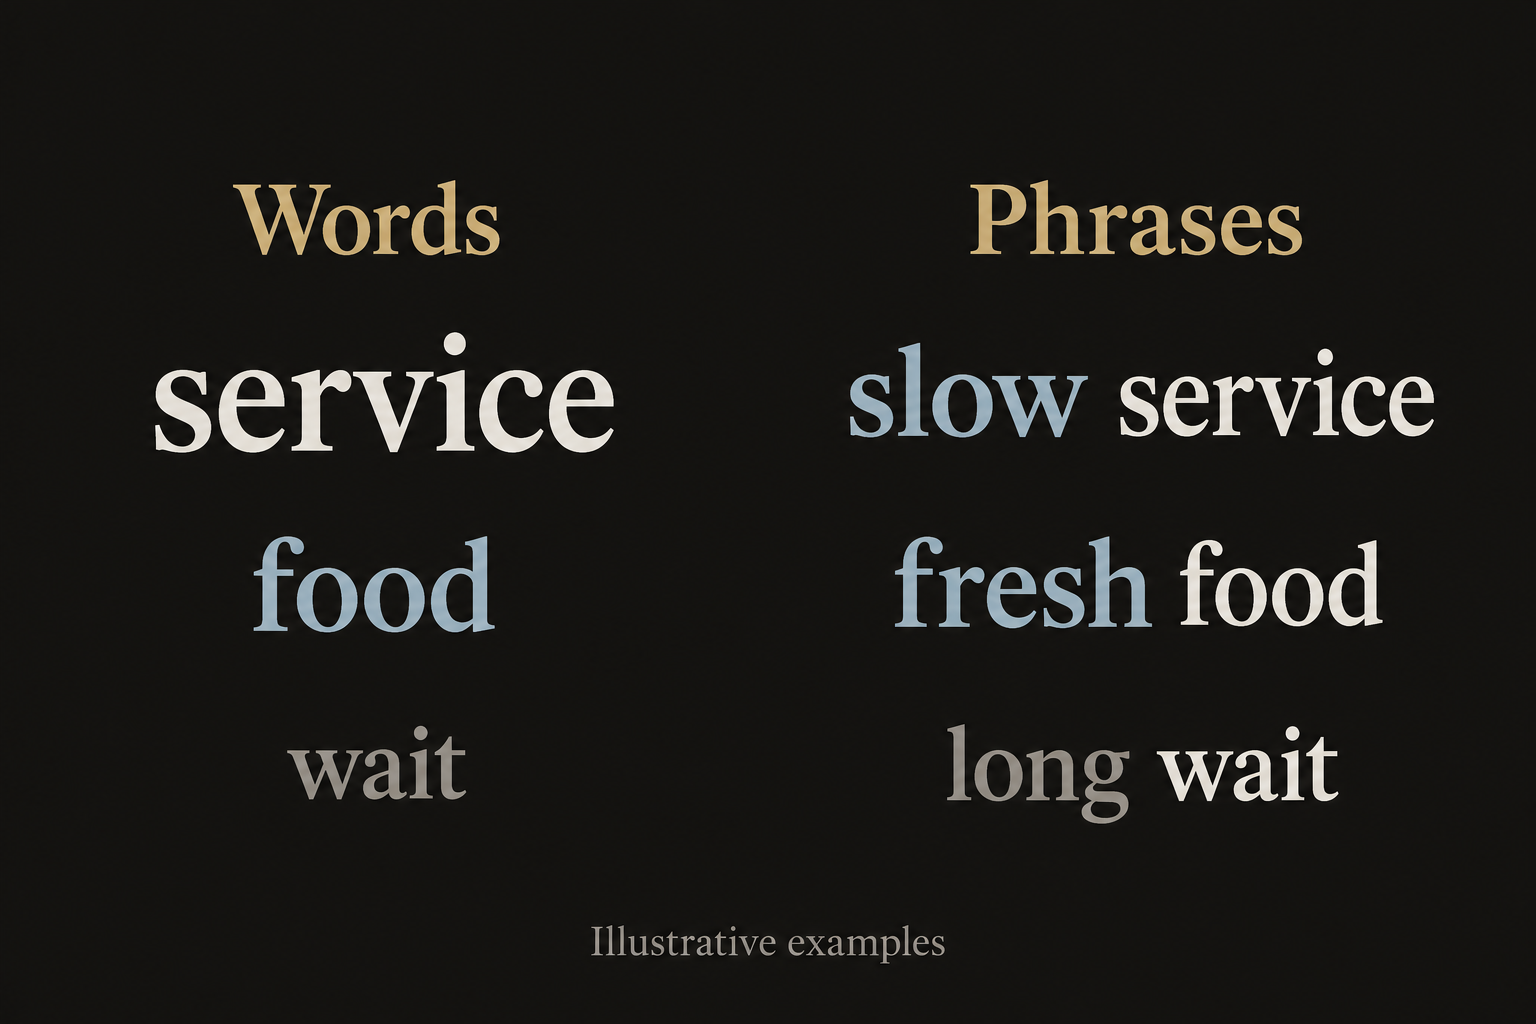
Frequent mentions of “service” do not yet distinguish praise from complaint. “Slow service” retains a relation. Adjective–noun pairs can therefore be useful for summarizing reviews, without being universally superior to bags of words. Extraction can fail, and irony, negation and longer contexts may still be lost.
Chapter 4: Putting local context back↗
4.1 Beyond a matching string↗
Retrieval can show the text around a hit as well as match a query, highlighting the query term within it. Keyword-in-context (KWIC) reconnects occurrence with use. SeeSoft and TileBars offer different historical examples in the related course material; they need not be treated as a current list of ready-to-use software.
The interface should provide a route back to the sentence. Otherwise, a striking word may come from a passage whose negation or quotation marks have disappeared.
4.2 WordTree: where repetition branches↗
Wattenberg and Viégas’s WordTree starts from a query word or phrase and organizes repeated following or preceding sequences as a tree. Shared prefixes merge before branching at different words. This is not a syntactic parse tree or simply a list of fixed-length n-grams.
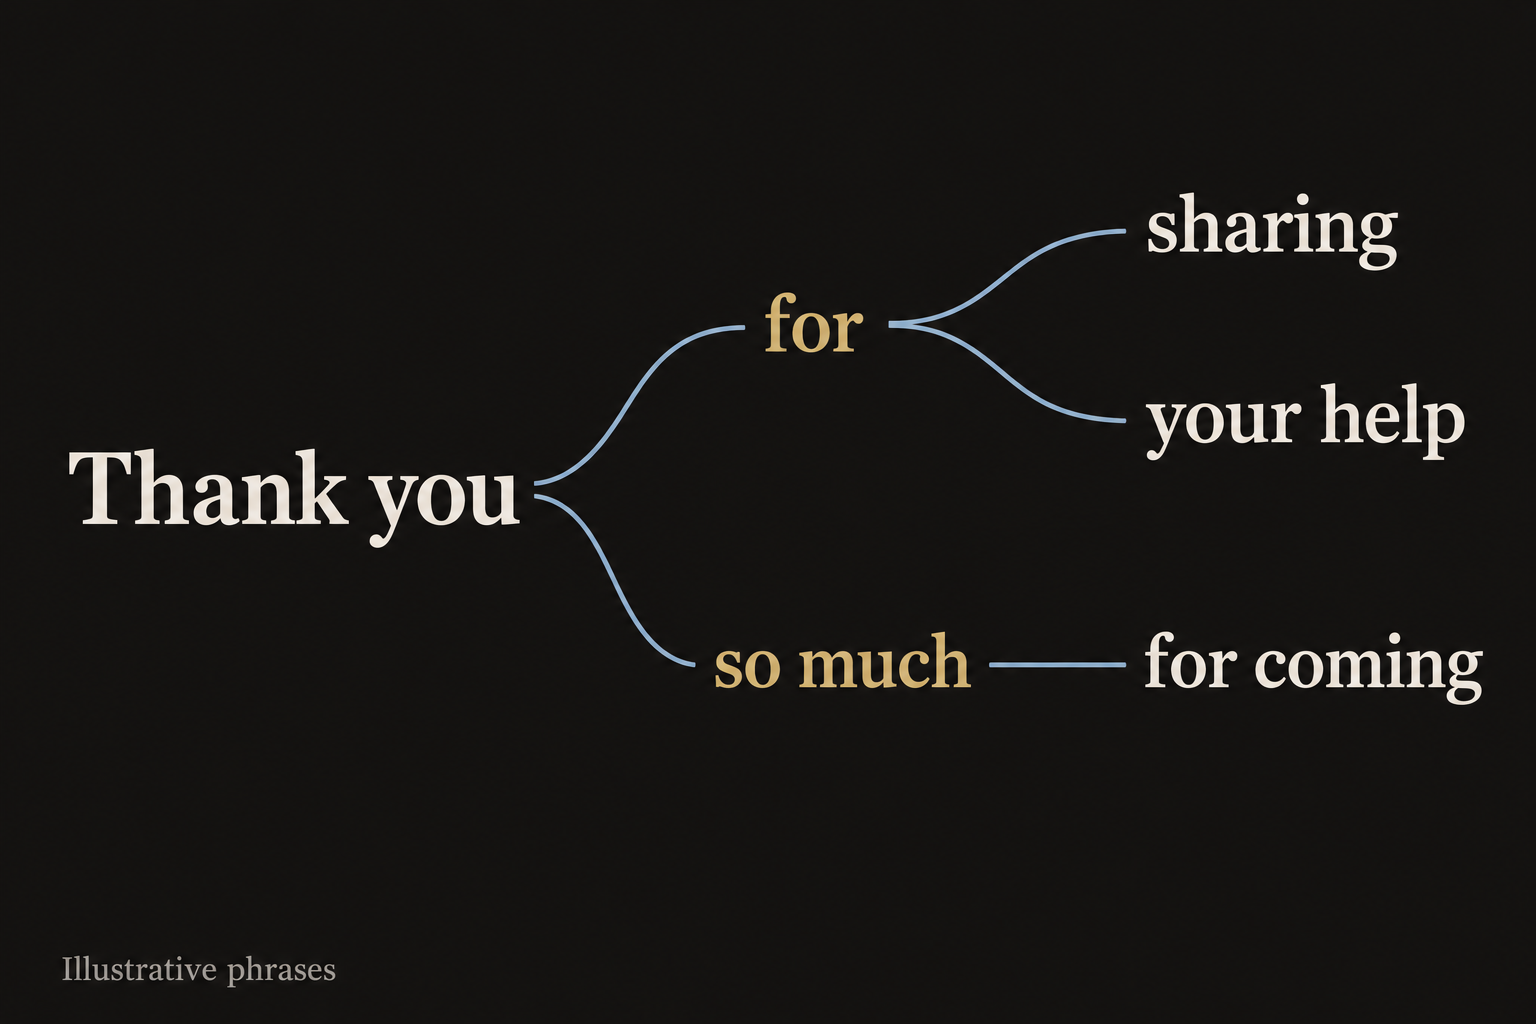
The starting point determines which local structures become visible. Exact matching separates lexical and syntactic variants. Filtering rare branches improves legibility, but the remaining display is no longer the complete distribution. Jason Davies’s interactive implementation offers a way to explore this form of querying.
4.3 Phrase Nets: define the relation first↗
Phrase Nets find a specified relation, such as “X and Y” or “X at Y,” or use the output of syntactic analysis. Matches become a node–link view. In the original design, occurrences can affect node size and pattern position can determine edge direction. Changing the pattern changes the network. See Mapping Text with Phrase Nets.
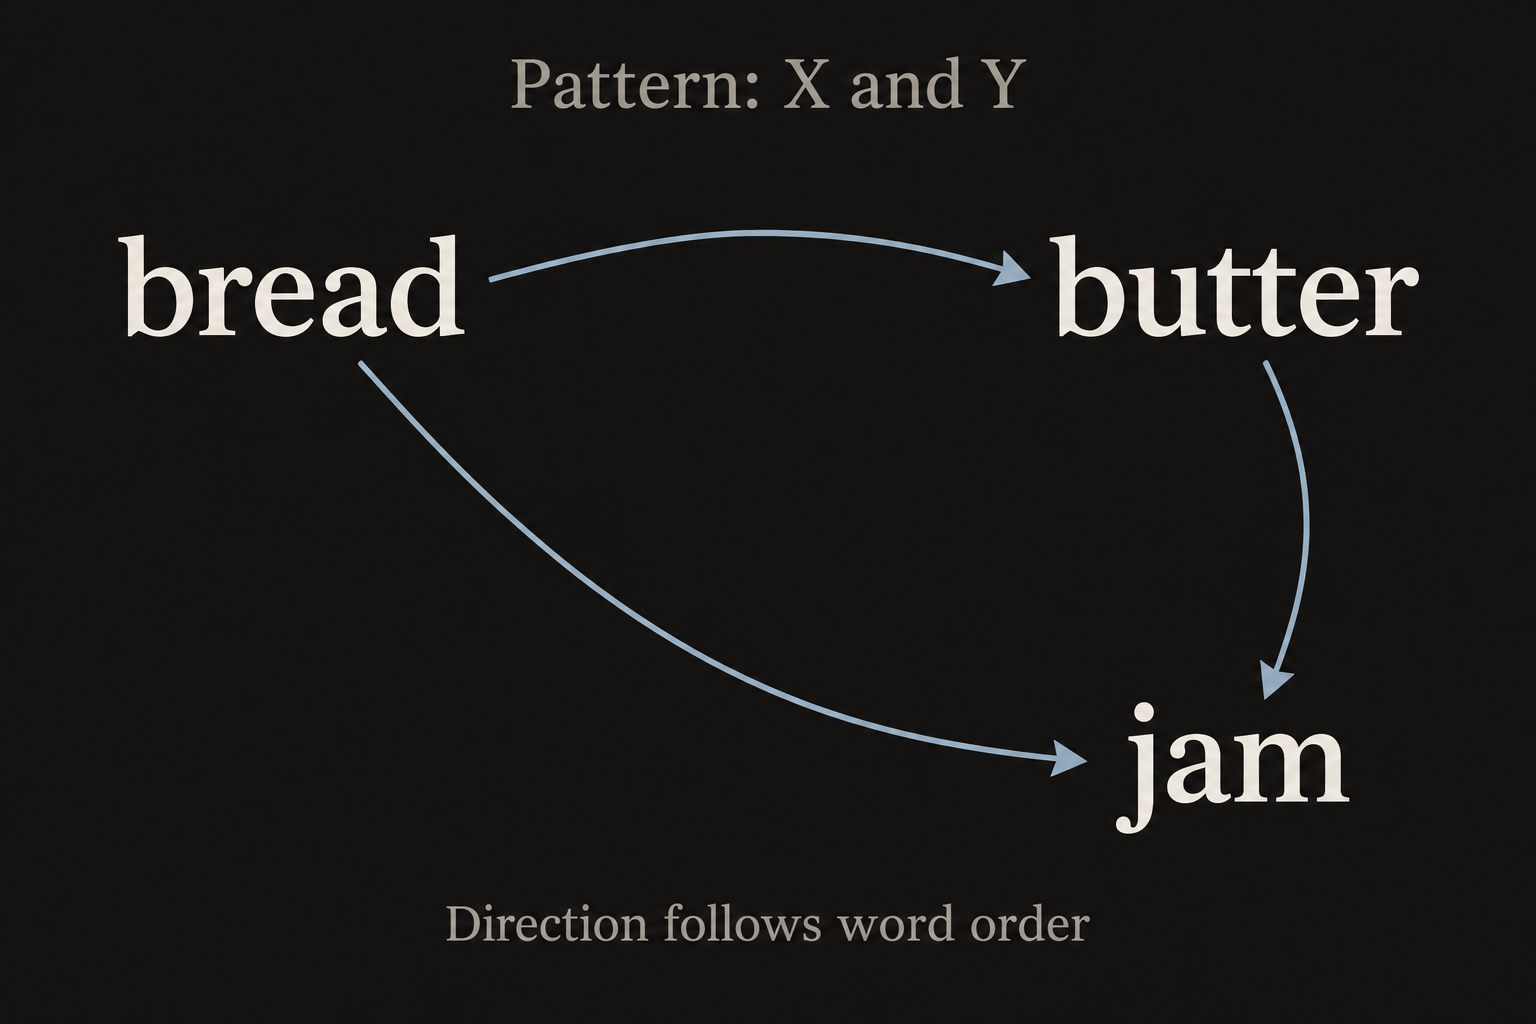
An edge first establishes a match to the chosen relation; it does not automatically establish a causal, psychological or social connection. The extraction rule belongs alongside the graph’s interpretation.
Chapter 5: Documents have positions, versions and participants↗
5.1 Content and interaction↗
| Perspective | Relations that may be retained |
|---|---|
| Within a document | Term position, sequence, paragraphs and hierarchy |
| Between documents | Similarities or groups computed from explicit features |
| Layout | Map selected relations into space without assuming every distance has semantic meaning |
| Interaction | Browse, brush, link views, return to passages and revise query patterns |
5.2 Beyond the final version↗
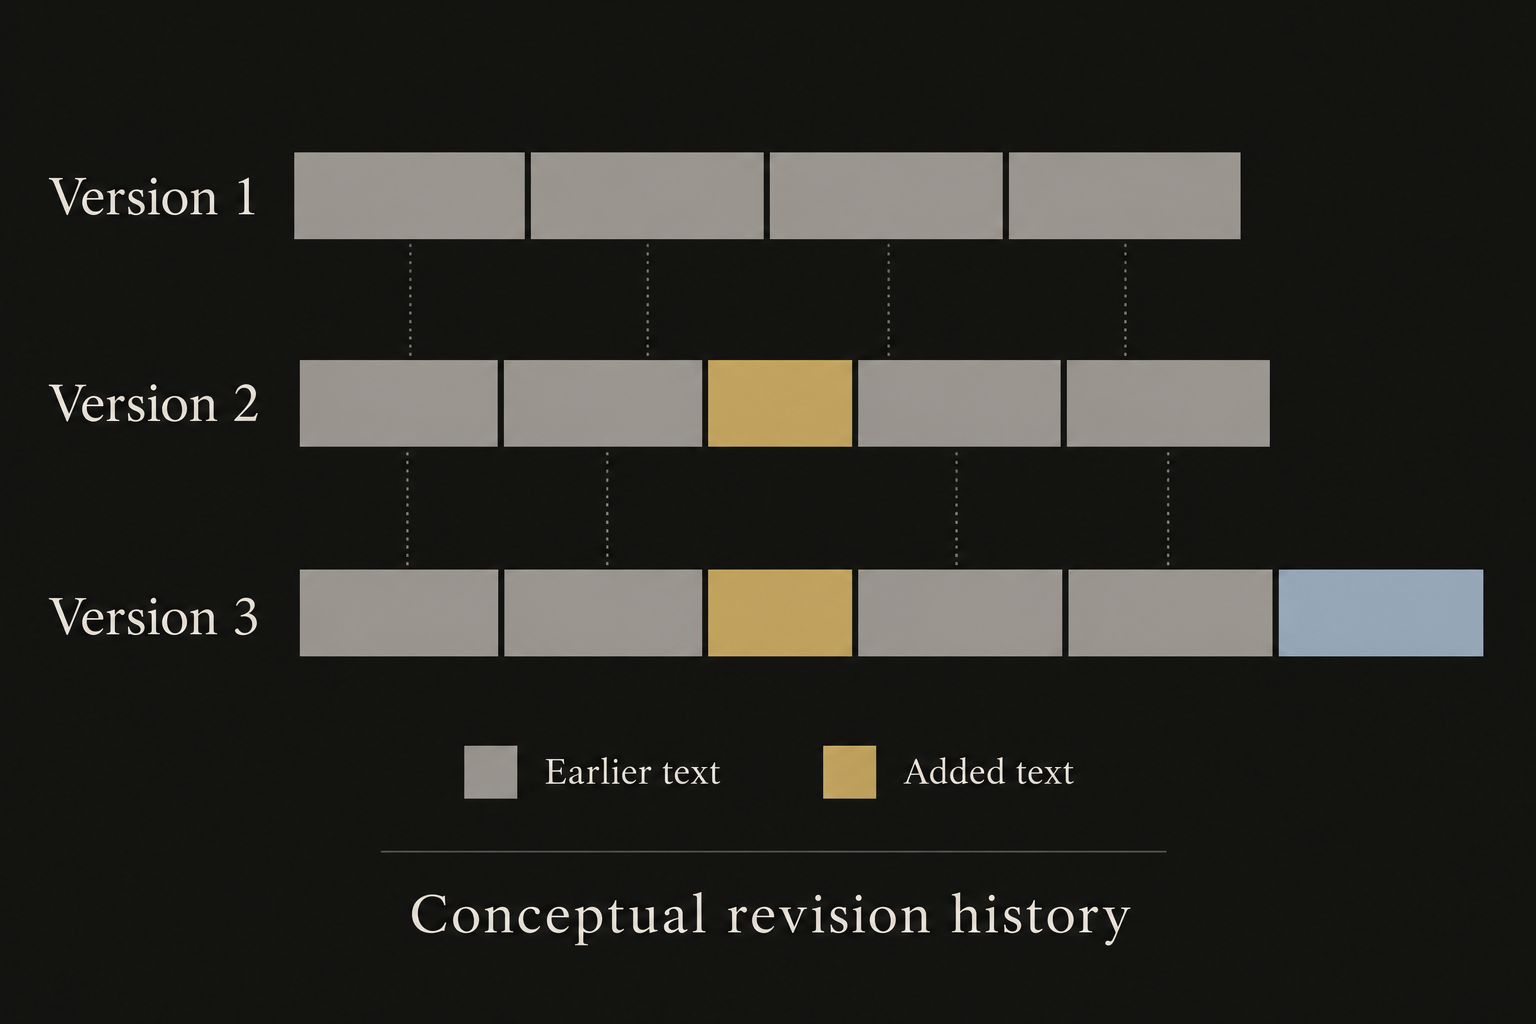
Revision records can reveal when passages were added, removed or retained. Wikipedia’s History Flow and Git histories concern different objects. Animation is one way to present time, rather than a requirement.
The original note illustrated this section with Ben Fry’s The Preservation of Favoured Traces, which follows six editions of On the Origin of Species, rather than Wikipedia edits. The schematic here does not use the book’s data; the original project remains available through the link.
5.3 Conversation: who, what and when↗
Conversations can be examined by sender and recipient, content, time and combinations of these dimensions. Message volume alone does not establish the quality of a relationship. Terms alone may not reveal who is replying to whom.
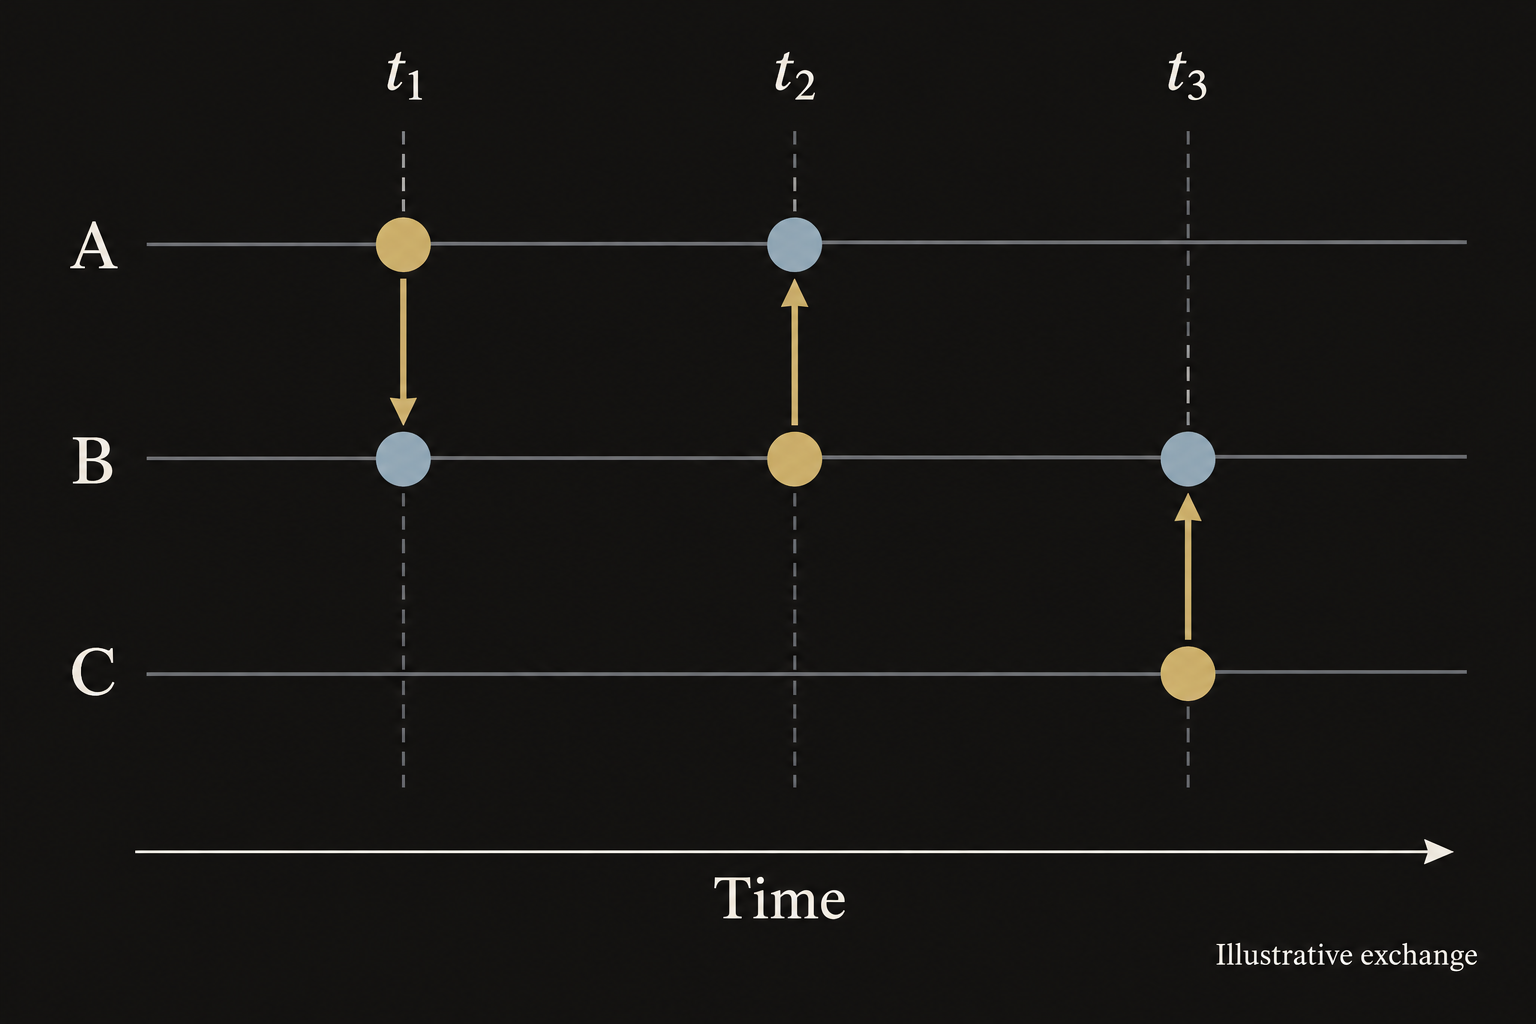
Historical designs include Newsgroup Crowds, AuthorLines, Mountain and Themail. Themail connects the terms in an email correspondence with time and provides access to the original messages. Such designs help formulate more specific reading questions without explaining an entire relationship on its participants’ behalf.
Chapter 6: From collections to latent topics↗
6.1 Comparing side by side↗
| Method | Question |
|---|---|
| Parallel tag clouds | Which terms stand out in each subset, and how does one term recur across groups? |
| Document projections | Which documents appear close in a low-dimensional view of a specified representation and distance? |
| Topic-model views | How do documents relate to topics, and topics to terms? |
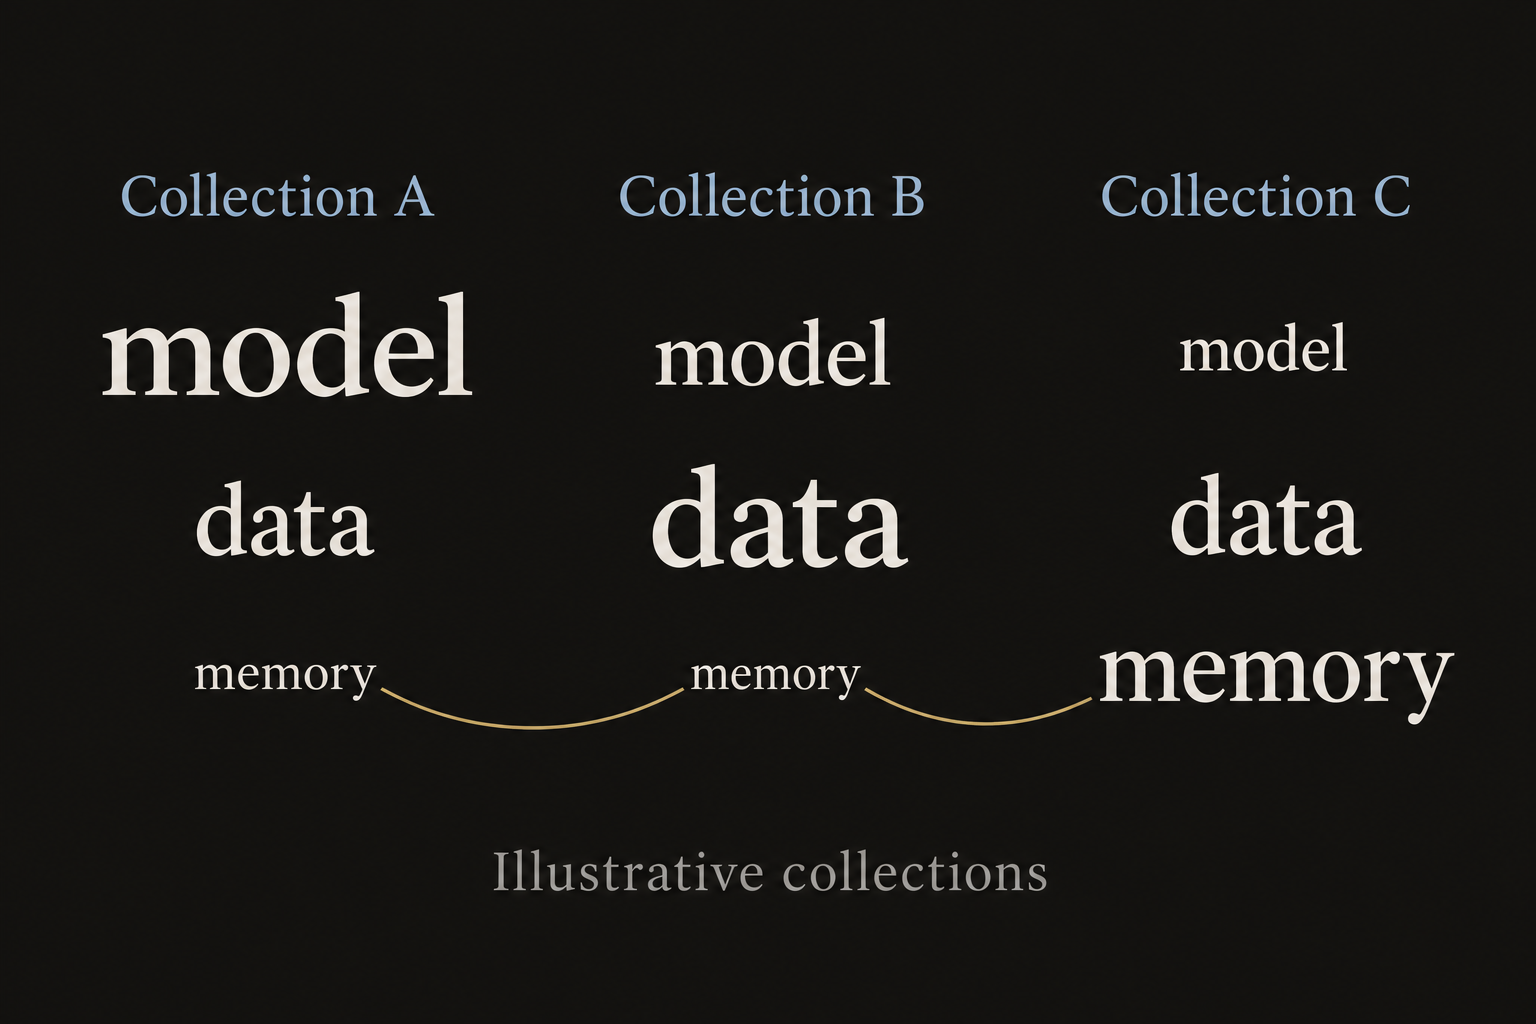
Collins and colleagues’ Parallel Tag Clouds combine a parallel layout with tag clouds and access to individual texts. Comparison involves more than placing independent clouds side by side. Term selection, weight scales, absences and cross-column tracing all affect what can be read.
6.2 LSA: a low-rank approximation↗
Latent semantic analysis (LSA) applies truncated singular value decomposition to a count or TF–IDF matrix. With documents as rows and terms as columns:
The dimensions of , and are , and . Retaining singular directions gives a lower-dimensional representation. This use of SVD does not make every direction a directly nameable probabilistic topic.
6.3 LDA: a mixture is not a classification↗
Latent Dirichlet allocation (LDA) is a generative model. A document has a mixture of topics; each topic is a probability distribution over the vocabulary. Given document ’s mixture weights and topic–term probabilities , the probability of a token taking value is:
Here , , and each topic satisfies , . This is a token-level mixture conditional on fixed parameters. Full LDA also includes a prior over document mixtures and inference. A document can involve several topics without being assigned to one exclusive class.
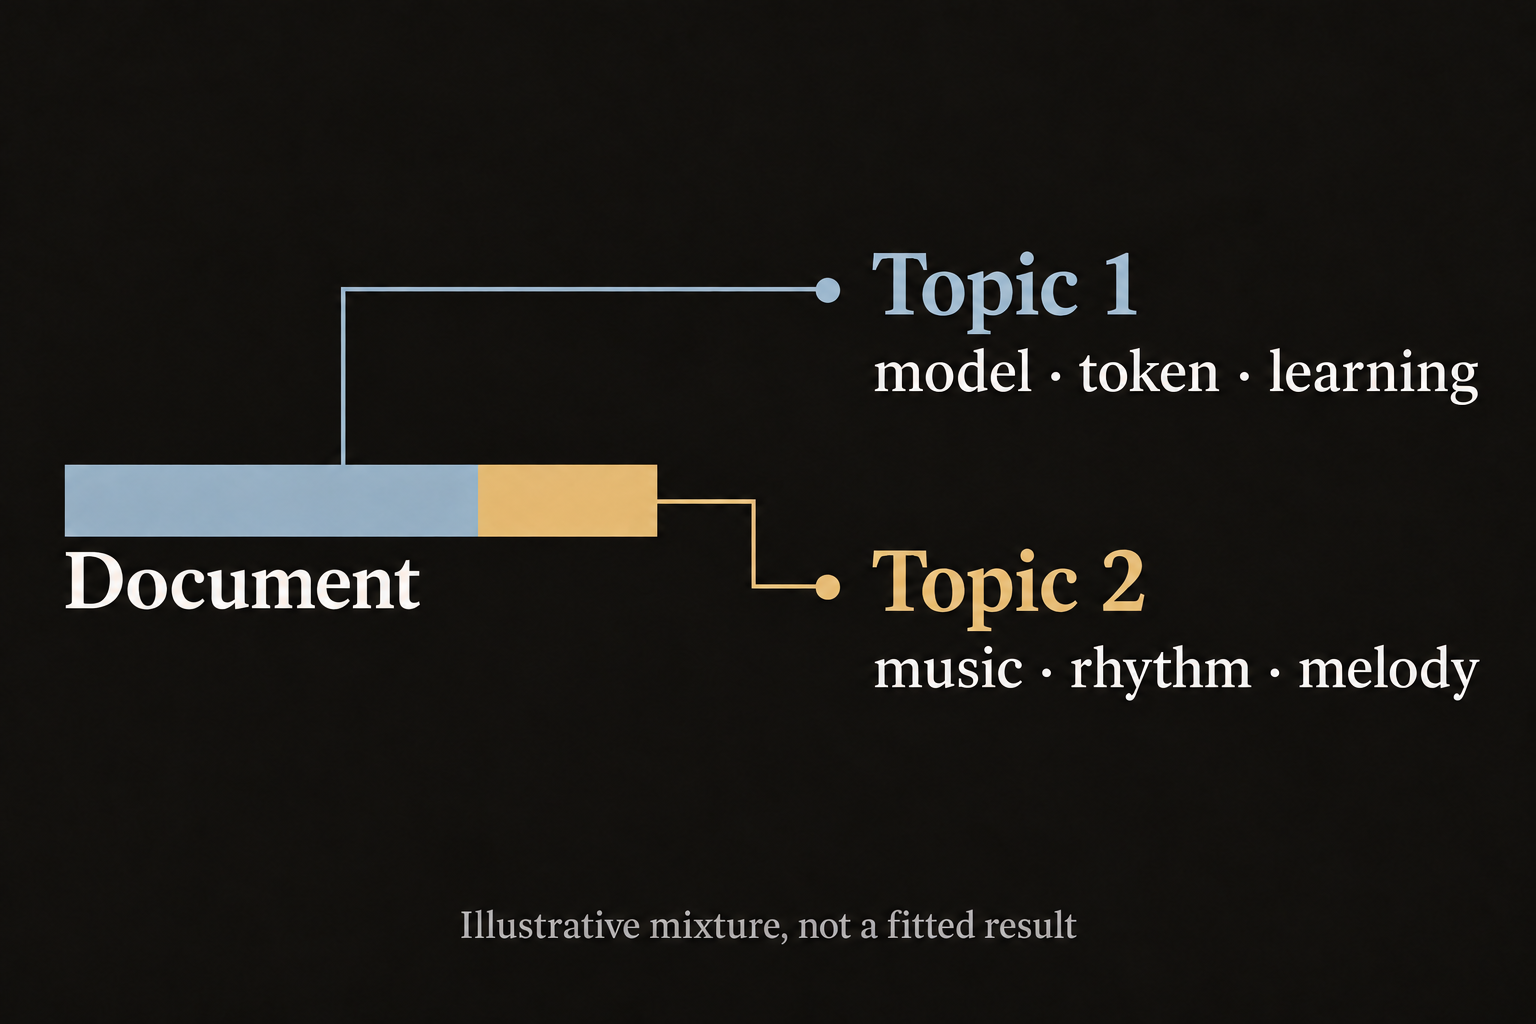
Calling a topic “cats” or “music” is an interpretation of its prominent terms, rather than proof that the model has acquired that concept. LDAvis links a topic overview to term views. Its two-dimensional distances depend on distributional comparisons and projection; the spaces between circles should not be mistaken for meaning itself.
Text has many forms. Each choice determines both what becomes visible and what still requires a return to the words.